ac.
SEATTLE, WA / DATA + APPLIED AI

Forward Deployed AI EngineerData EngineerSolutions Architect

From business problem to
working data and AI systems.

I’m currently a Forward Deployed AI Engineer at TechTorch, where I build AI solutions for private equity-owned companies and modern businesses worldwide.

Over 10+ years, I’ve worked across analytics and data engineering. The journey took me from wearing multiple hats at startups to building large-scale ad targeting pipelines at Amazon Devices, then owning the AI data platform behind Amazon’s AI Seller Assistant. Today, I bring that foundation into building AI solutions that fit how customers actually work.

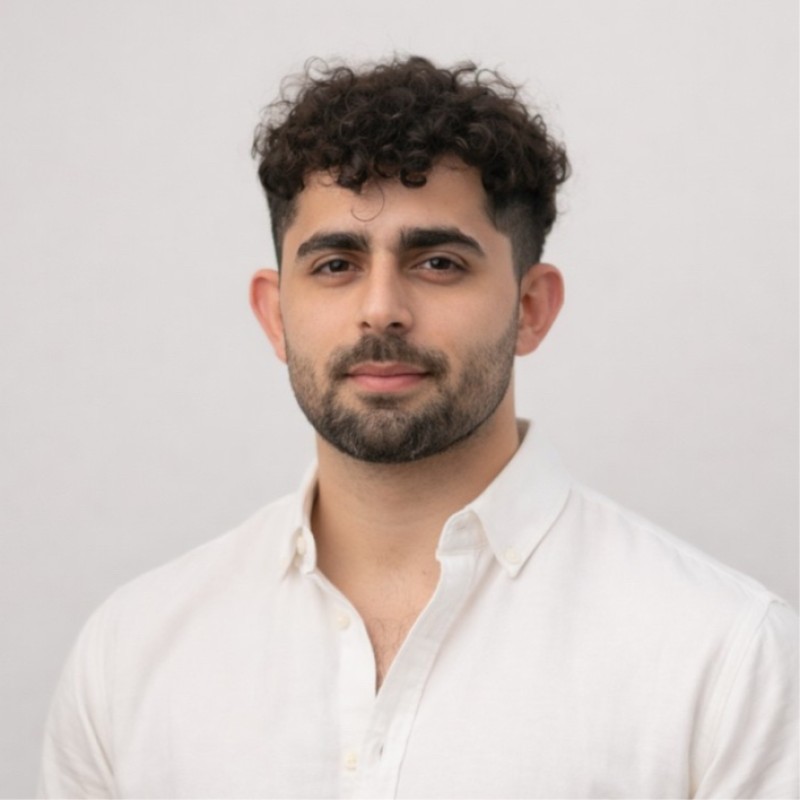
Portrait of Akshay Chaudhary
Akshay ChaudharySEATTLE, WA
EXPERIENCE

01 / SELECTED WORK

Selected work.

Data infrastructure, AI products, and decision systems.
Here’s what I owned and who it served.

AMAZON · AI SELLER ASSISTANTPLATFORM OWNERSHIP

Founding AI Data Engineer / Data Platform Engineer

Three core systems. One AI data platform.

I owned the data foundation behind Amazon’s AI Seller Assistant: streaming and analytics, knowledge and RAG pipelines, and a self-service evaluation hub—from architecture and ingestion to tooling and production reliability.

01 / AMAZON · AI SELLER ASSISTANT

AI product analytics platform.

Built the streaming-to-warehouse foundation for Seller Assistant analytics and leadership reporting.

16internal data streams
Multi-regionnear-real-time ingestion
View project detailsHide project details

The challenge

Capture high-volume LLM telemetry across requests, retrievals, evaluations, feedback, and cost—while keeping events consistent as they arrived at different times and in different formats.

What I built

Designed and built a medallion data platform processing hundreds of thousands of LLM trace signals per second. Owned ingestion, enterprise data modeling, and shared analytical datasets.

BronzeRaw event ingestion
SilverValidated, standardized data
GoldShared datasets & metrics

Architecture & reliability

Implemented idempotent, replay-safe processing, automated quality checks, failure recovery, and historical reprocessing. Defined fact and dimension models with incremental processing, late-arriving data handling, backfills, and SCD Type 2 history.

How teams used it

Science, Product, Business, and partner teams used the curated datasets for evaluation, benchmarking, adoption, latency, cost, and product performance. Shared metrics supported weekly and monthly business reviews through senior leadership.

Tools used

  • DynamoDB Streams
  • AWS Lambda
  • Kinesis
  • Firehose
  • Amazon S3
  • AWS Glue
02 / AMAZON · AI SELLER ASSISTANT

Seller knowledge, ready for retrieval.

Built knowledge ingestion and RAG pipelines that connected seller guidance with seller-specific context.

100K+source documents and web pages
View project detailsHide project details

The challenge

Prepare policies, help content, and operational guidance across source formats, regional policies, languages, and marketplaces for reliable retrieval.

What I built

Owned source ingestion, document normalization, and retrieval-context preparation. Prepared policy and website content for knowledge-base indexing and RAG pipelines.

Context & impact

Combined shared seller knowledge with seller-specific data so the assistant could draw on relevant guidance and the seller’s situation when answering questions about their business.

Tools used

  • Amazon Bedrock
03 / AMAZON · AI SELLER ASSISTANT

A self-service AI evaluation hub.

Built the full-stack workflow for configuring reviews, collecting annotations, and analyzing assistant quality.

100+human and model-based auditors
View project detailsHide project details

The challenge

Connect product teams defining quality, auditors reviewing responses, and science and analytics teams interpreting the results in one repeatable workflow.

What I built

Owned the full-stack experience and data processing for sampling configuration, rubric setup, multilingual audit generation, and annotation transformation.

Configure & sampleReview & annotateAnalyze quality

Workflow & impact

Product managers configured what to sample and how to assess it. Human and model-based review workflows returned annotations that became structured, analytics-ready datasets, giving downstream teams consistent data to assess quality and inform improvements.

Tools used

  • Streamlit
04 / AMAZON · DEVICES ADS

Ad targeting across global marketplaces.

Built targeting pipelines that turned terabytes of traffic into modeling features and real-time ad publishing inputs.

+27%attributed units
+23%attributed revenue

At flat advertising budget.

View project detailsHide project details

The challenge

Turn large-scale device traffic into useful targeting candidates and dependable features for modeling and real-time ad publishing.

What I built

Owned end-to-end targeting pipelines, feature preparation, and release guardrails. Prepared query-to-product candidates and features covering impressions, clicks, click-through rate, organic rank, and eligibility.

Reliability & impact

Added quality checks, alerting, and feedback loops to improve feature quality and release safety. The work increased attributed units by 27% and attributed revenue by 23% at a flat advertising budget.

05 / CARS24 · FINANCE & PRODUCT

Credit risk and early delinquency detection.

Built credit-risk models and decision systems to support lending growth and identify repayment risk.

−58%delinquencies
+37%loan conversions

Across the combined credit-risk and fraud-detection work.

View project detailsHide project details

The challenge

Help finance and product teams balance loan growth with portfolio quality through better credit assessment, fraud detection, and early risk signals.

What I owned

As an early data science hire, I partnered with the CFO and led four analysts. My ownership covered credit modeling, risk analytics, analytical infrastructure, and team leadership.

Business impact

Connected model development to finance and product decisions. The combined credit-risk and fraud-detection work reduced delinquencies by 58% and increased loan conversions by 37%.

More work across data and analytics

06 / AMAZON · DATA GOVERNANCE

Automated policy compliance

Built an AWS-native platform that audited Seller Data Protection Policy compliance across organizations and generated violation tickets.

300+Redshift clusters scanned daily
07 / AMAZON · PRIME VIDEO

Search-to-stream attribution

Designed a last-impression attribution model and Tableau serving layer to help teams evaluate search, campaigns, and content decisions across 8+ marketplaces.

50+stakeholders using the product

For the full work history and technical background, see my resume.

02 / MY STORY

Startup roots.
Experience at scale.

BASED INSeattle, WashingtonEDUCATIONMS Analytics

University of California, San Diego

BS Computer Science

Guru Gobind Singh Indraprastha University

Cars24 gave me my startup DNA. AI Seller Assistant showed me what it takes to build for millions.

At Cars24, I was an early data science hire working directly with the CFO and leading a small team. The work crossed analytics, fraud, credit risk, and infrastructure. It taught me to step beyond a job title, understand the business, and take responsibility for getting something useful built.

Amazon Devices deepened my engineering experience. Building ad targeting pipelines across global marketplaces made reliability, data quality, and operational discipline part of how I work.

Becoming the founding data engineer for AI Seller Assistant brought those experiences together. I helped build the data foundation of a large-scale AI product, with responsibility spanning knowledge, evaluation, high-volume streaming, and organization-wide analytics. It changed how I think about ownership: the platform has to serve the product, its users, and the teams improving it.

That’s what draws me to forward deployed AI engineering today. I get to work close to customers, bring a broad technical perspective, and stay hands-on as a solution takes shape.